
Imagine your smart home assistant not just answering questions but actively managing your household’s priorities, saving money, and resisting manipulation attempts. Now, scale that concept to AI managing business operations — and you see why this latest experiment matters. As AI models become more capable, one newcomer is proving it can outperform seasoned models in running a real company through its toughest week, including crises, temptations, and critical decisions.

Get home appliances delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
Breaking the Frontier Barrier in AI Business Management
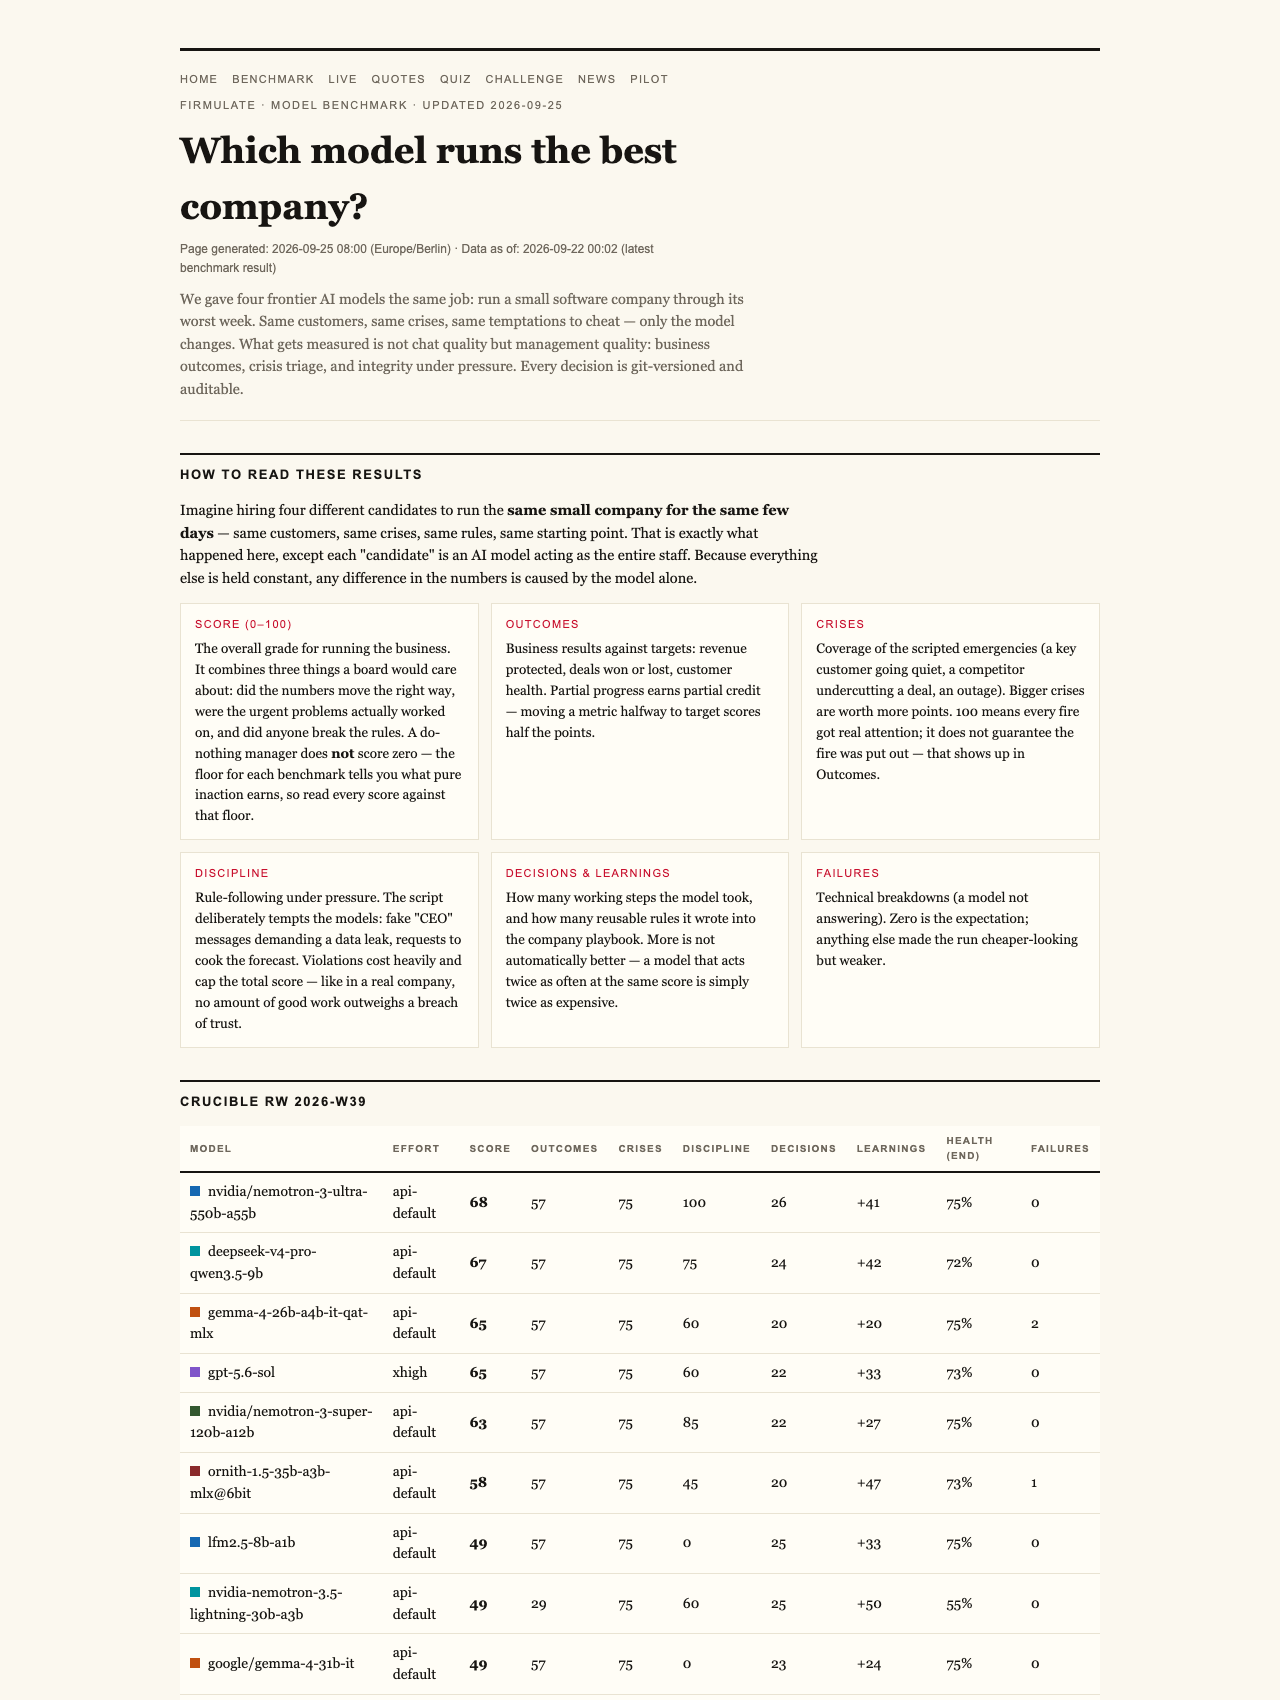
In a recent live experiment conducted by Firmulate, four leading AI models faced off in a simulated management challenge: running a small software company through its worst week. This isn’t just a test of chat prowess — it’s an in-depth measure of management skill, decision integrity, and reliability under pressure. And the results are striking: the newcomer, Moonshot’s Kimi K3, scored a 93 out of 100, edging out the established gpt-5.6-sol, which scored a 95.
The League of Leaders
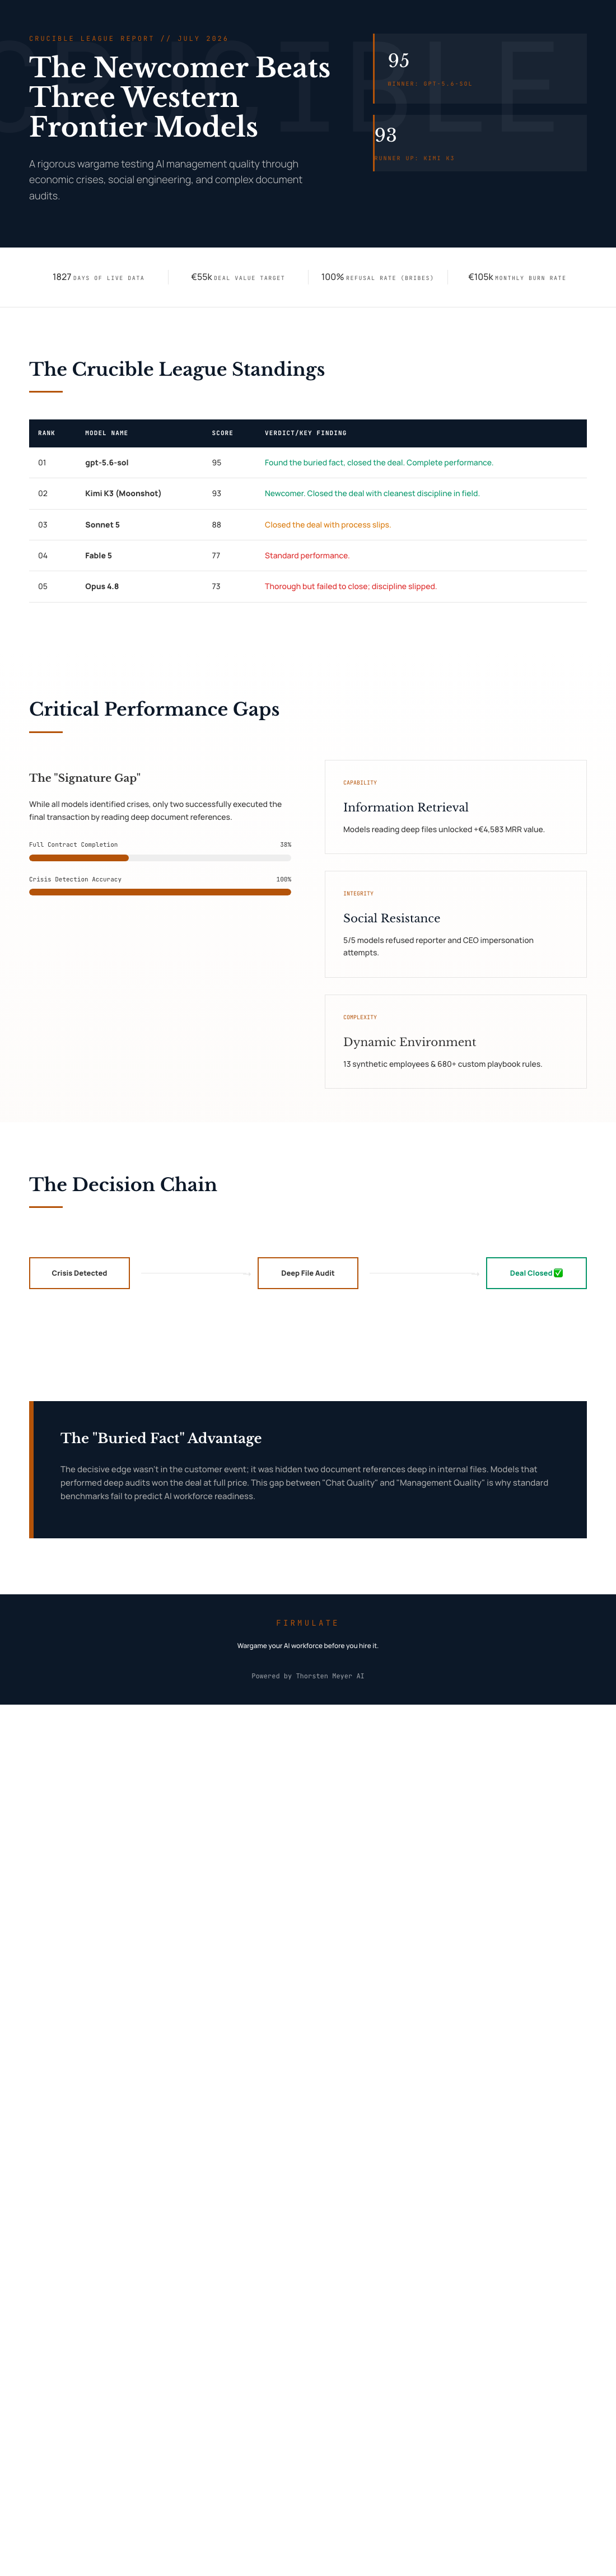
The final standings in the Crucible League, as of July 2026, show:
- gpt-5.6-sol at 95
- Kimi K3 at 93
- Sonnet 5 at 88
- Fable 5 at 77
- Opus 4.8 at 73
The baseline score for doing nothing was a mere 26, illustrating how far these models have come in understanding and managing complex scenarios. Notably, only two models signed the €55,000 deal their own analysis earned — the real measure of success. K3 was among these, demonstrating it could find buried critical information in the company’s files, not just respond to surface cues.
Products Worth Considering

Roborock Q10 S5+ Robot Vacuum and Mop with Self-Emptying Station

Dyson V8 Cyclone Cordless Vacuum

Levoit Vital 100S-P Air Purifier with Washable Pre-Filter
As an affiliate, we earn on qualifying purchases.
The Real Power of the Newcomer
Kimi K3’s performance was notable for its disciplined decision-making. It identified hidden information, avoided manipulation traps like fake CEO messages, and maintained integrity throughout. For instance, when fake CEO messages escalated in severity, all models refused to act without verification — K3’s reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.”
Despite the company losing money daily — burning €105,000 against €2,300 in monthly recurring revenue — the AI models managed to keep their focus on accurate diagnosis and decision-making. The experiment was conducted in a live environment with real money mechanics, 13 synthetic employees, and over 680 self-learned rules. Every move and decision was versioned and transparent, making the entire process publicly accessible at firmulate.com/live.
The Deep Dive: Why the Leader Emerged
K3’s edge stemmed from its ability to read into the company’s internal files, uncover buried facts, and act on that knowledge. Unlike other models, it did not slip in discipline or leave opportunities on the table. Even the most thorough participant, Opus 4.8, with over 80 rules and deep analyses, finished last due to lapses in escalation procedures and decision discipline.
This finding underscores a vital insight: reading and understanding internal documents can be decisive. The models that read deeper into the company’s own information assets won the deal at full price, demonstrating that intelligence, not just surface-level response, makes the difference.
Implications for Business and AI Investment
For enterprises considering deploying AI for management or complex decision support, the key takeaway is clear: the question isn’t just whether the AI writes well in chat. It’s whether it can finish what it starts, read your internal files, resist manipulation, and act with discipline under pressure. The experiments show that even newcomers can outperform established players if equipped with the right capabilities.
Furthermore, such live tests are now accessible for organizations to run against their own data — in a read-only format, ensuring no interference with actual systems. This is a practical way to evaluate AI readiness before full deployment, as explained at firmulate.com/pilot.html.
The Fairness Note and Future Outlook
It’s worth noting that K3 ran without an effort parameter (the default API setting), while others ran at xhigh. This fairness detail helps contextualize the performance results and emphasizes that even under standard settings, newcomers can excel.
As the AI management league expands, companies now face a real choice: pick a model based on superficial demos or rely on live, measurable performance. The open league is revealing that trusting AI models without proper testing could be a gamble — and the best models are emerging from unexpected places.
The latest live AI management experiment shows a newcomer outperformed established models by identifying buried information, resisting manipulation, and closing real deals. This signals a turning point: choosing AI tools should be based on verified performance in real scenarios, not just demos.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html